Evaluating MCP Gateway Vendors for Enterprise Deployment
Gateways fill MCP's security gaps by enforcing identity and policy on tool calls.
MCP gateway evaluation comes down to one question: does the product resolve every tool call to a real identity in your directory and enforce policy on it before the call executes, or does it just move traffic faster? The protocol itself ships with no authentication, no rate limiting, no audit logging, and no access control, so any enterprise running agents against MCP servers without a gateway in between is running an ungoverned system by design. The vendor field has split into three shapes, hyperscaler-native, edge-native, and dedicated governance platforms, and the right one depends on how your infrastructure is built.
Why MCP's protocol gaps make a gateway mandatory
MCP defines how an agent finds a tool, then calls it. It does not define who that agent is, how many times it may call that tool per minute, or where a record of the call ends up afterward. Authentication, rate limiting, audit logging, and access control are absent from the base spec. Every direct connection from an agent to a tool is, by construction, an exposure nobody is watching.
That absence plays out concretely once more than one person is writing agents. Each developer machine has its own list of MCP servers, each agent service has its own API tokens, and no one keeps a central inventory of either. Security cannot revoke one team's access without hunting down every machine that team touched. Nobody can answer, after the fact, which agent called which tool, because nothing recorded it.
This is not a complaint vendors invented to sell software. The official MCP 2026 roadmap names audit trails, enterprise-managed authentication, and gateway or proxy patterns as open problems the protocol has not solved. OWASP's MCP Top 10 for 2025 catalogs the resulting attack classes by name: tool poisoning, rug pulls where a tool is silently redefined after approval, tool shadowing, a cross-server variant of shadowing filed under MCP03, insufficient authentication and authorization under MCP07, and intent flow subversion, the formal name for prompt injection, under MCP06. The NSA published its own MCP Security Design Considerations document in May 2026, walking through prompt injection, trust boundary failures, access control gaps, token security, and sandboxing recommendations across the protocol.
None of this is exotic. It is what happens when a protocol built to let models call tools gets deployed in organizations that also need to know who did what. A gateway is where that gap closes. Treat it as formalized infrastructure for running MCP in production, the same way a reverse proxy is not optional once a web service has more than one user who shouldn't see everyone else's data.
The two jobs every enterprise buyer needs a gateway to do
An MCP gateway does two distinct jobs beneath the marketing copy, and most of the confusion in vendor evaluation comes from comparing products on one job while ignoring the other. The first job is enablement: handling authentication to every upstream tool once instead of per person per client, offering a catalog of connectors, giving developers a path to turn internal APIs into tools, and reaching systems that sit behind a private network. The second job is governance: resolving who is actually behind a given tool call, deciding which clients get to connect at all, enforcing which tools a given role may invoke, and writing down what happened afterward in a form an auditor can read.
Enterprise platforms tend to describe this as a layered control plane, so not a single box. One common structure puts an LLM gateway at the bottom, handling API routing, key protection, budget limits, and guardrails; an MCP gateway in the middle, governing agent-to-tool interactions and which tools are visible to which identity; and an agent gateway on top, governing autonomous agent orchestration and session-level policy. All three layers share identity management, cost telemetry, and audit policy, so if you change a permission in one place, it's enforced everywhere, not just three times. Gartner's October 2025 report on Agent Management Platforms describes something structurally similar: a central hub where governance, performance, and value converge, sitting above the agent execution layer and supplying runtime governance, observability, and financial intelligence.
One architectural distinction separates the products that actually govern from the ones that only watch. An inline gateway sits directly in the request path and inspects, and enforces policy on, every call in real time. A sidecar or an out-of-band monitor reads logs after the fact and can flag a problem, but it cannot stop the call before damage is done. Buyers should ask, point blank: can this product block a call before it executes, or does it only report on the call afterward?
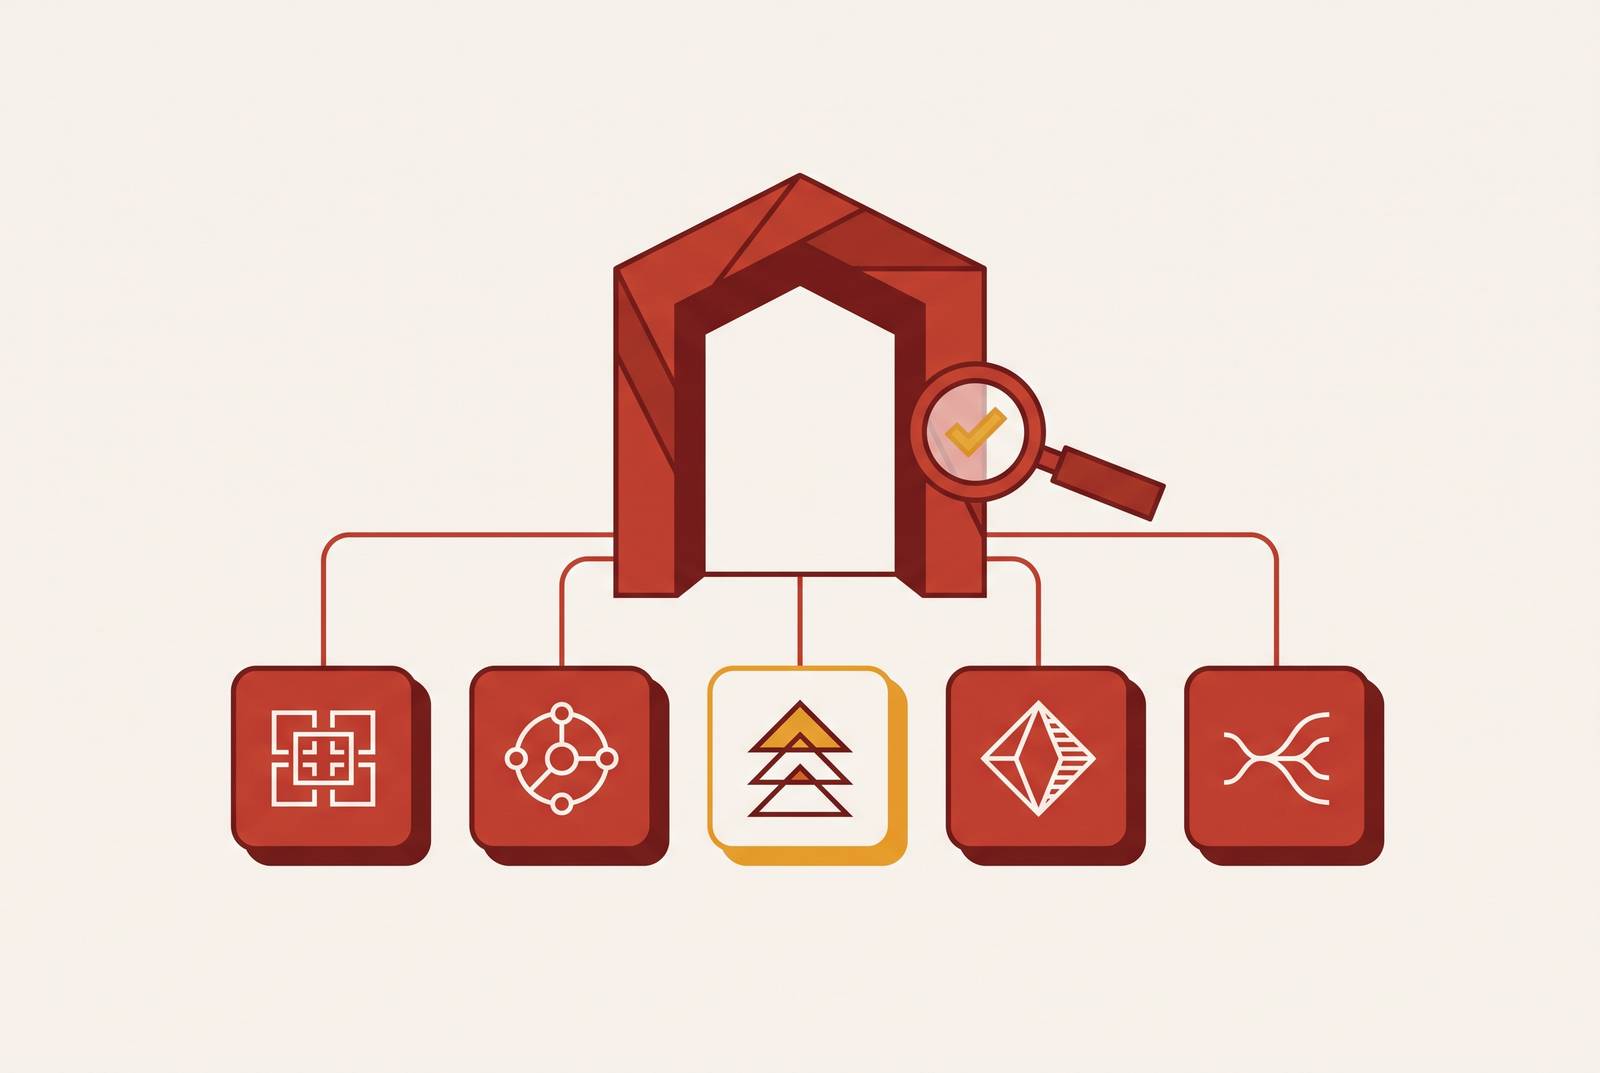
This two-job split is also how the rest of this evaluation is organized. Session management, connector depth, distribution, and private network reach measure how well a vendor enables agents to get work done. Identity depth, policy granularity, audit quality, threat detection, and observability measure how well a vendor governs what they do once they're enabled. A gateway can score well on one cluster and poorly on the other, and buyers who only look at one end up surprised later.
How the vendor market has split
Before you compare features, ask which shape of gateway your infrastructure actually calls for, because the wrong shape costs more than any feature gap inside the right one. The market has settled into three recognizable patterns.
Hyperscaler-native gateways are the obvious choice for a company consolidated on one cloud. AWS AgentCore Gateway turns OpenAPI, Smithy, and Lambda endpoints into MCP tools and handles inbound and outbound OAuth without extra code. The tradeoff is scope: AgentCore governs what flows through AWS and nothing that doesn't. A developer who plugs an open MCP tool into Cursor on a Tuesday afternoon never touches it.
Edge-native gateways suit distributed teams already running on Cloudflare One. Cloudflare's enterprise MCP reference architecture combines Cloudflare Access, MCP Server Portals, Cloudflare AI Gateway, and Cloudflare Gateway into one stack for organizations whose MCP servers already live at the edge.
A third pattern, existing platform extension, answers the question for some buyers without a new vendor. A company that already runs Kong in front of its APIs can use Kong's AI MCP Proxy plugin, which converts existing REST APIs into MCP tools with no server code. Kong's existing OpenID Connect, rate limiting, and logging plugins apply to the new MCP endpoints the same way they applied to the old REST ones. There is no new vendor, no new security audit, and no fresh procurement cycle. The AWS case follows the same logic: AgentCore makes tools out of what's already described in OpenAPI or Smithy, but it governs only what passes through the AWS boundary.
That boundary is where the fourth shape, dedicated governance platforms, competes. Whatever a hyperscaler or edge gateway receives is, by definition, not the whole picture: shadow AI tools, servers nobody registered, personal-account usage that never touched the sanctioned path. Speakeasy is in this dedicated governance category, built specifically to govern, track, and enforce rules across AI agents, MCP servers, and agentic workflows wherever they run, within or beyond one cloud's perimeter. That's a different job than AgentCore's or Cloudflare's, not a better version of the same one. The question to answer before any demo is whether the organization is single-cloud enough for a hyperscaler gateway to see everything that matters, or multi-cloud and multi-vendor enough that a federating layer is the only way to get one policy surface across all of it.
Session management and connector depth: the enablement criteria that decide day-one adoption
A gateway that governs perfectly but frustrates developers will get routed around, and the ungoverned path wins the moment it's easier than the governed one. That's the test for every criterion in this section: does it lower friction enough that the governed route is also the fastest route?
Session management is the first filter. A gateway that is worth deploying takes over authentication to every upstream tool, so a user signs in exactly once, the gateway itself acts as the OAuth client to each downstream service on the user's behalf, it stores and refreshes upstream tokens without asking again, and it falls back to a shared API key for services that have no concept of per-user OAuth. But does this work against third-party servers the vendor never built, and can the gateway present a modern OAuth flow to clients even when the upstream server it's talking to has none? If a product only handles session management for its own first-party connectors, it fails this test immediately.
Connector depth splits into two kinds, and you need both, each for its own reason. Catalog connectors are the SaaS tools employees expect to use on day one, and a vendor either hosts them directly or offers them through a marketplace. Internal connectors turn a company's own APIs into MCP tools, and this is where gateways diverge sharply in practice. Some convert an existing API contract into tools automatically with no server code required. Some generate and host a server from that contract. Some package a server the engineering team already wrote into a container. Some require a fully running MCP server with credentials in place before setup can even start. That difference decides whether the platform team becomes a bottleneck every time a new internal system needs to be exposed to an agent. AWS AgentCore Gateway builds tools from OpenAPI, Smithy, and Lambda endpoints; Microsoft's Foundry Agent Service surfaces remote MCP servers from a tool catalog and republishes a curated set behind one MCP-compatible Toolbox endpoint. Neither approach is wrong, but they ask for very different amounts of engineering work before the first tool goes live.
Distribution decides how fast any of this actually reaches employees. The floor is a URL someone pastes into a config file by hand, and that works, but it doesn't scale past a handful of early adopters. Above that floor sit plugins or bundles that install servers directly into Claude Code, Cursor, or Codex through their own marketplaces, role-based assignment so a person's tool set shows up correctly without a support ticket, and device agents or managed settings that push configuration out to a whole fleet of machines at once. A governed path that nobody can find loses every time to an ungoverned one that's a single copy-paste away, which is the entire adoption problem in one sentence.
You should check private network reach, but don't let it dominate the evaluation. Most systems worth connecting to an agent sit behind a firewall, and the options are a tunnel or private link, a self-hosted data plane, or running the gateway entirely on-premises. For healthcare, financial services, or government buyers, air-gapped or on-prem deployment is a hard requirement, full stop. For most other buyers it's a secondary consideration.
Auth conformance belongs in this section too, because it's a baseline enablement check as much as a security one. The MCP authorization specification requires servers to implement RFC 9728, Protected Resource Metadata, and requires clients to implement RFC 8707, resource indicators. A vendor sitting a full revision behind on either requirement will fail a security review on that basis alone, regardless of how good the rest of the product looks in a demo.
Identity integration depth: where governance-ready vendors separate from developer tools
Every governance capability downstream, role-based access control, audit trails, revocation, depends on one prior fact: can the gateway tie a tool call to a real person in the organization's identity provider, or only to a key or user record the gateway itself invented. That single question separates developer tools from governance-ready infrastructure faster than any other in this evaluation.
A principal that lives only inside the gateway is fine for a proof of concept and a genuine liability once the system is in production, because revoking a person from the company directory does nothing to the key that gateway issued separately. Enterprise-grade identity integration means the gateway consumes groups directly from the identity provider through SAML, OIDC, or SCIM, rather than maintaining a second, parallel role system that quietly drifts out of sync with the real one within a quarter. On-behalf-of identity has to survive nested calls too: when an agent calls a tool that itself calls a second tool, the original human's identity and permission scope should travel through that whole chain, rather than being swapped out for a broader agent credential partway through.
The identity provider landscape itself has moved recently. Okta's Agent SSO became generally available on August 24, 2026, and it brings the open Cross App Access standard into a first-class identity model for AI agents at the moment they connect, bundled into Okta's core SSO plans and backed by a large existing enterprise customer base. Microsoft's answer is Entra Agent ID, which provisions automatically for agents born inside certain Microsoft platforms, including Microsoft Foundry and, starting in July 2026, new Copilot Studio agents, and applies Conditional Access and blueprint-level policy across entire fleets of agents at once, enforcing the distinction between on-behalf-of and fully autonomous token patterns. If an organization's agent estate runs overwhelmingly on Microsoft infrastructure, Entra Agent ID is the path it can take with the least friction. But if an organization runs a genuinely mixed stack, the added cost of an identity-neutral gateway buys something Entra Agent ID structurally can't offer across non-Microsoft systems.
Several products already compete on this exact axis. Bifrost supports identity-based governance against Okta, Microsoft Entra, Keycloak, Zitadel, Auth0, Google Workspace, or any generic OIDC provider, with SCIM 2.0 directory sync built in. Speakeasy's control plane integrates with existing identity providers, including Okta and Entra ID, through role-based access control and identity enforcement wired directly into the gateway, so policy gets expressed in the same directory the security team already manages, not rebuilt from scratch inside a new tool. That distinction decides whether access control scales cleanly across teams and third-party integrations, or hits a wall the first time a new team or vendor joins: is RBAC tied to the identity provider an organization already runs, or is it siloed inside one vendor's authentication model?
The sharpest test of all of this is revocation timing. When someone's access is pulled or an agent version is deprecated, the change has to take effect on the very next call, not whenever the next sync job happens to run. Ask any vendor directly what the revocation latency is and how it gets enforced. A vague answer there is itself the answer.